Your AI Tech Lead.
Production-ready code from Day 1.
Spec-driven development, enforced. Claude Code writes code fast: TLM Forge makes sure it's correct: a spec audit before any code, independent multi-agent review of your plan and your diff, and a commit gate that blocks any code no reviewer has seen.
The engineering discipline of a senior staff team, enforced on every feature.
It shipped. Nobody checked it.
- A missing auth check nobody flagged
- An untested edge case in production
- A review that never actually happened
TLM Forge checks it before it ships.
Every change with real logic gets an independent, adversarial review: a gate, not a best effort.
From your request to shipped,
one disciplined pipeline.
After install you manage none of this. TLM Forge hooks into your Claude Code flow: it syncs the architecture and gets your diagram signed off before a line of code is written, then puts the finished diff through a parallel, adversarial review wave drawn from its Review Council before anything ships.
It gets sharper the longer it works with you.
TLM's memory layer persists across every session and project: architectural decisions, past bugs, and the conventions it learned the hard way. The proof is spec accuracy: the share of your work TLM anticipated before you wrote it.
Spec Accuracy Over Time
Spec accuracy = what percentage of your work was anticipated by TLM's spec.
The gap is bugs, unplanned features, and missed edge cases. The line goes up because TLM learns from every commit.
Discipline, enforced:
not politely suggested.
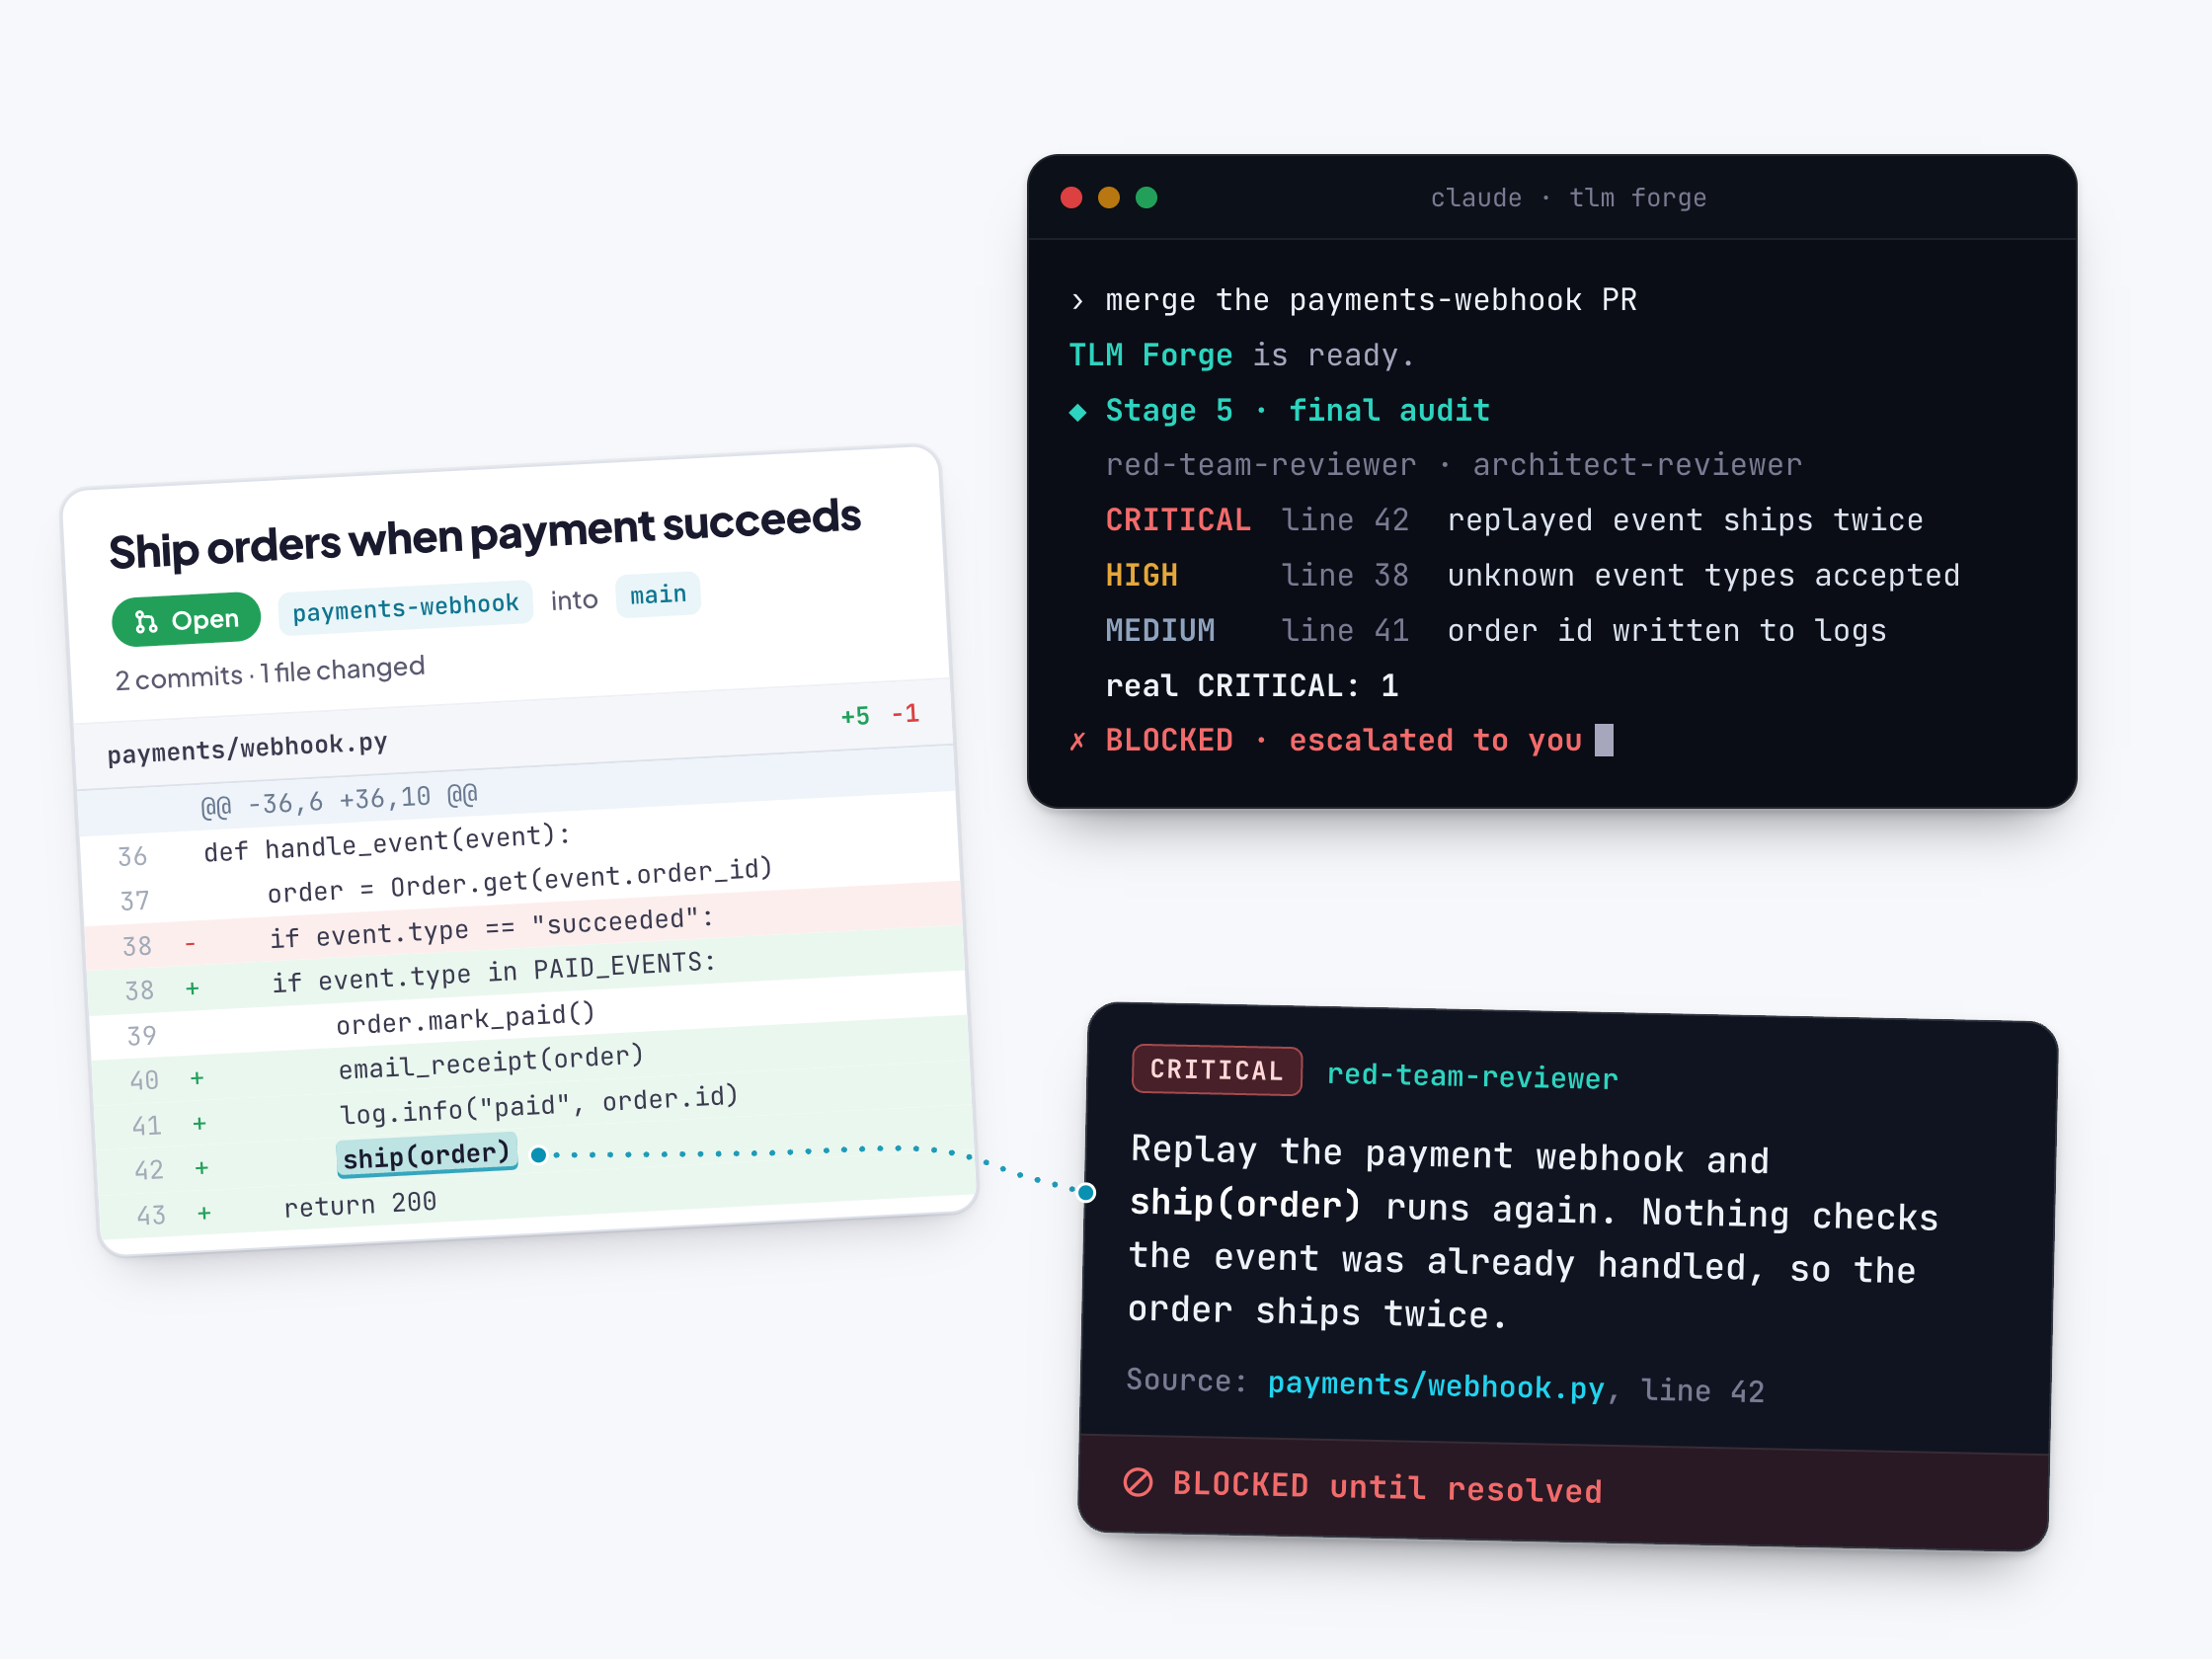
Most tools recommend good practice and hope you follow it. TLM Forge builds it into the pipeline and backs the key gates with hooks: independent adversarial review, tests first, and a final review wave whose CRITICAL and HIGH findings are fixed, or brought to you, before work ships.
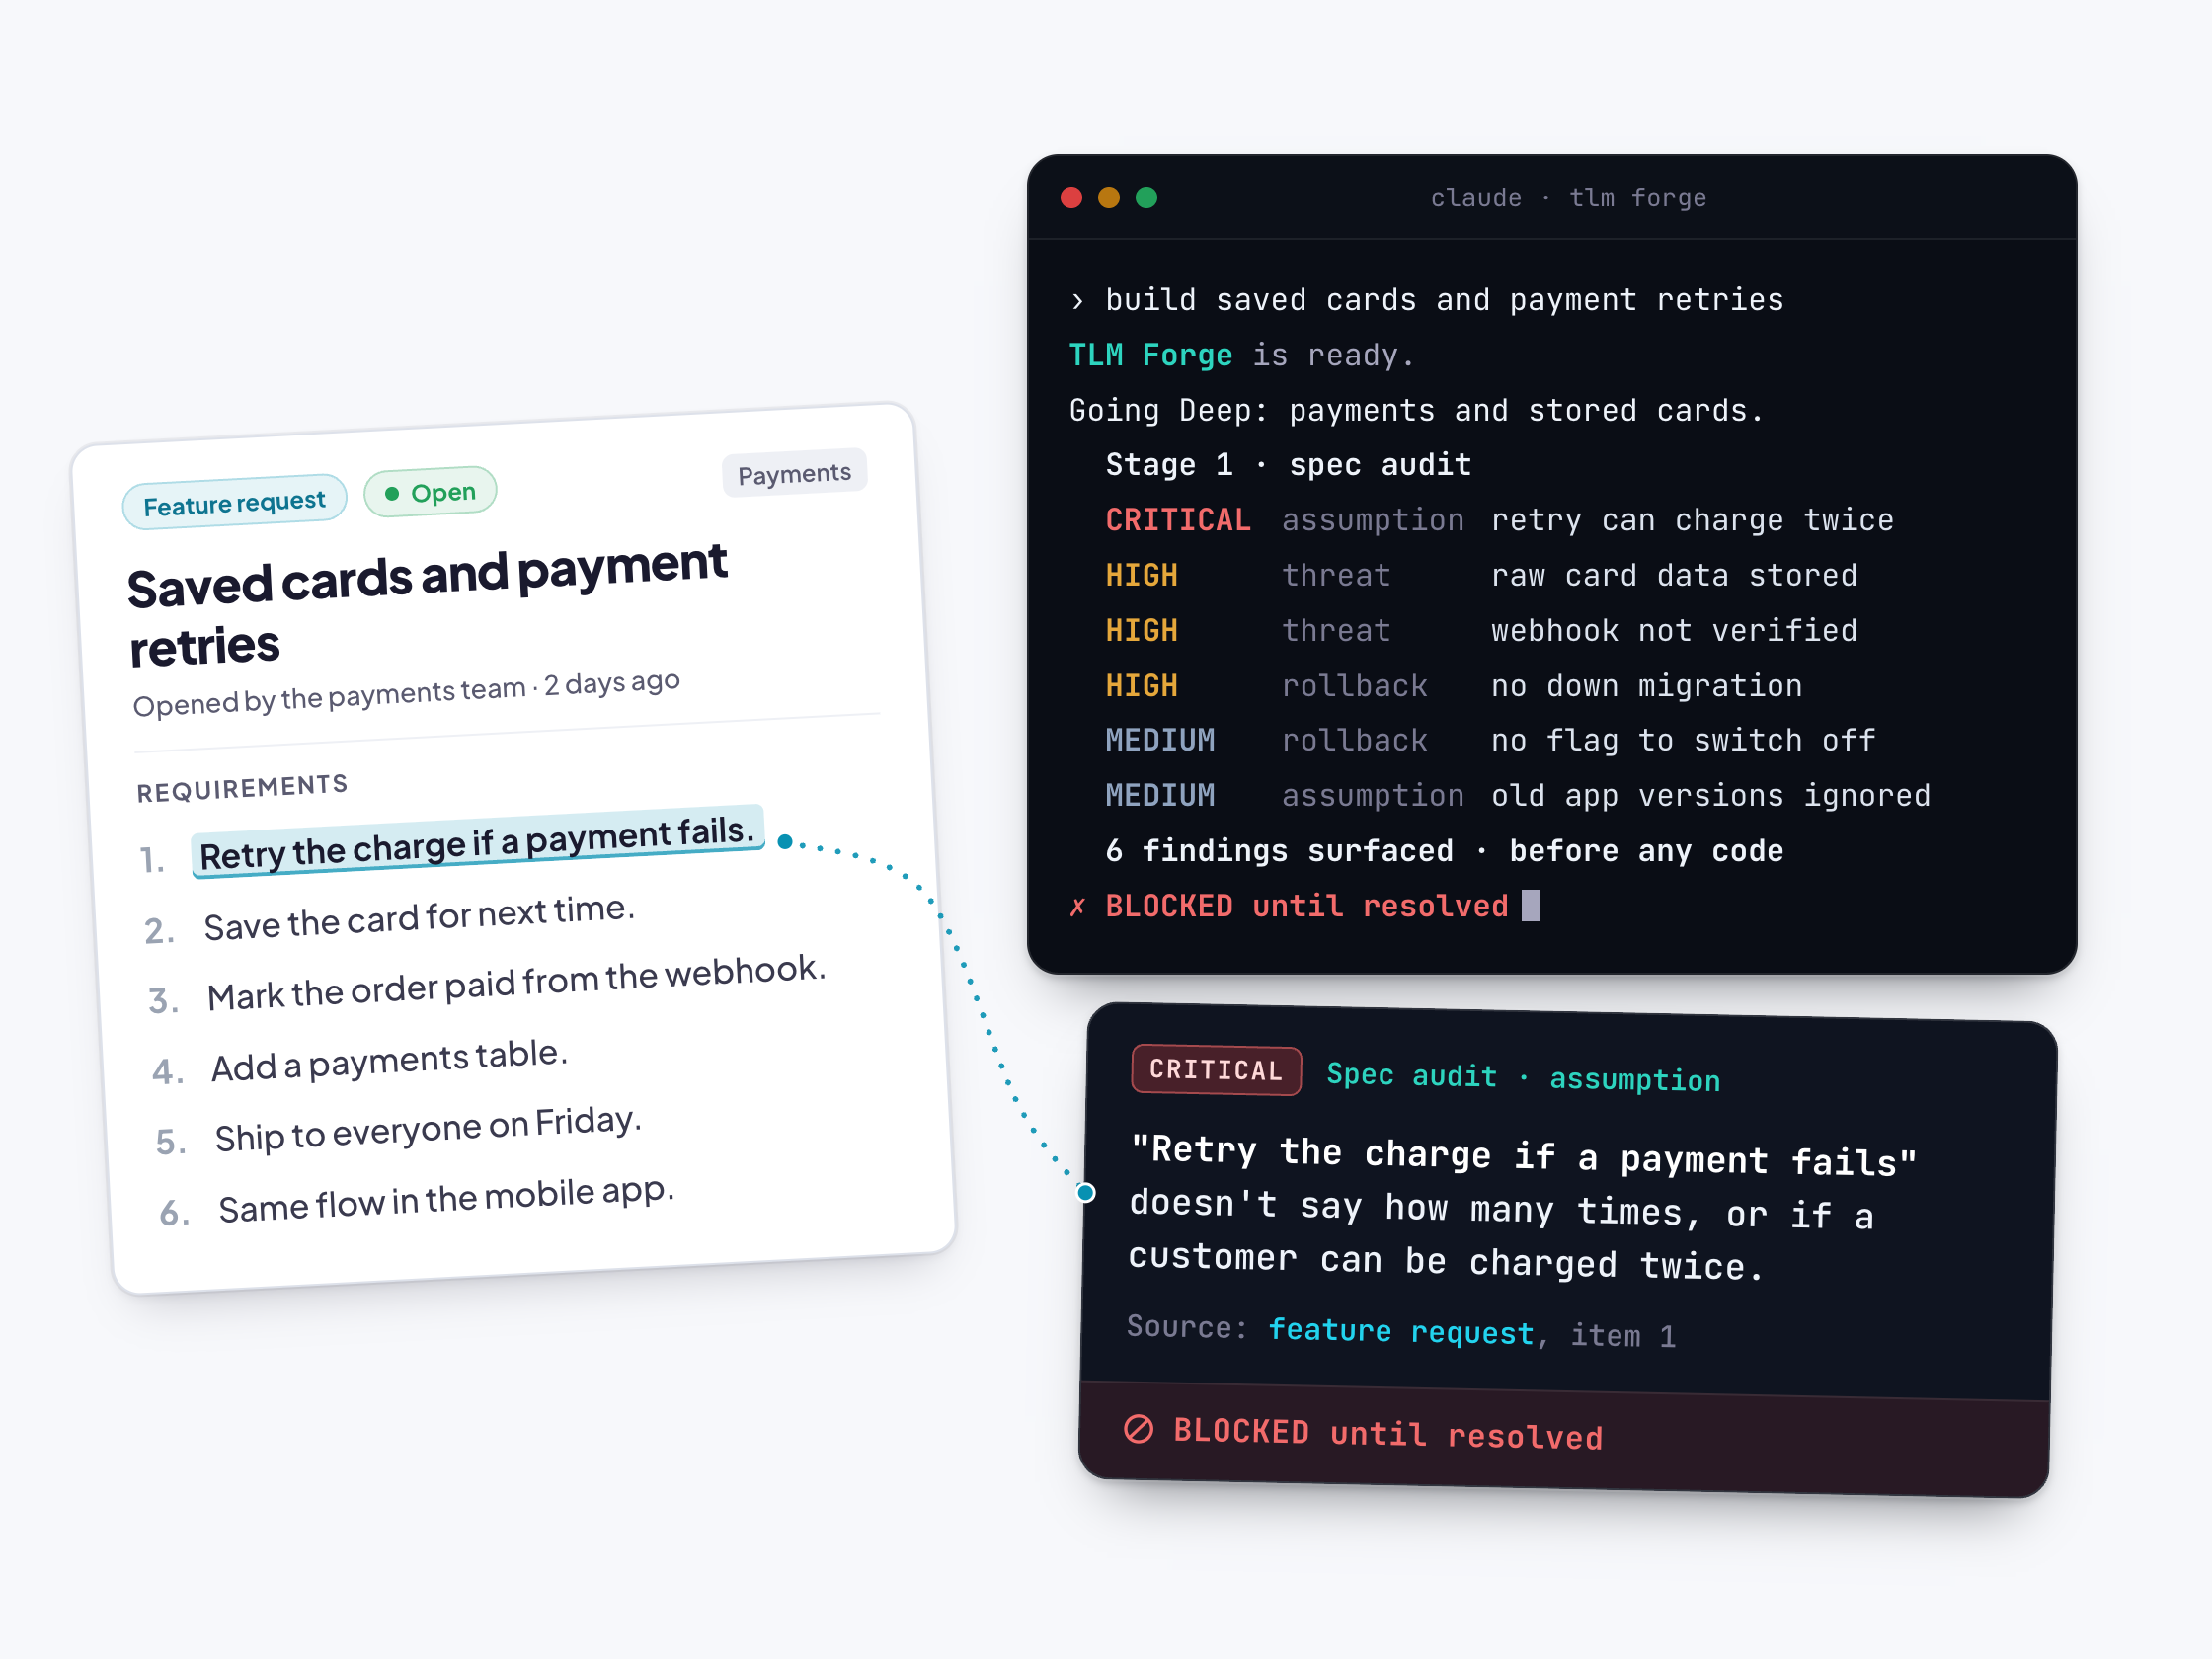
Spec audit before any code
Deep work starts with an audit of hidden assumptions, threats, and rollback risk, before a line is written. Medium work gets a shorter written analysis of the fix.
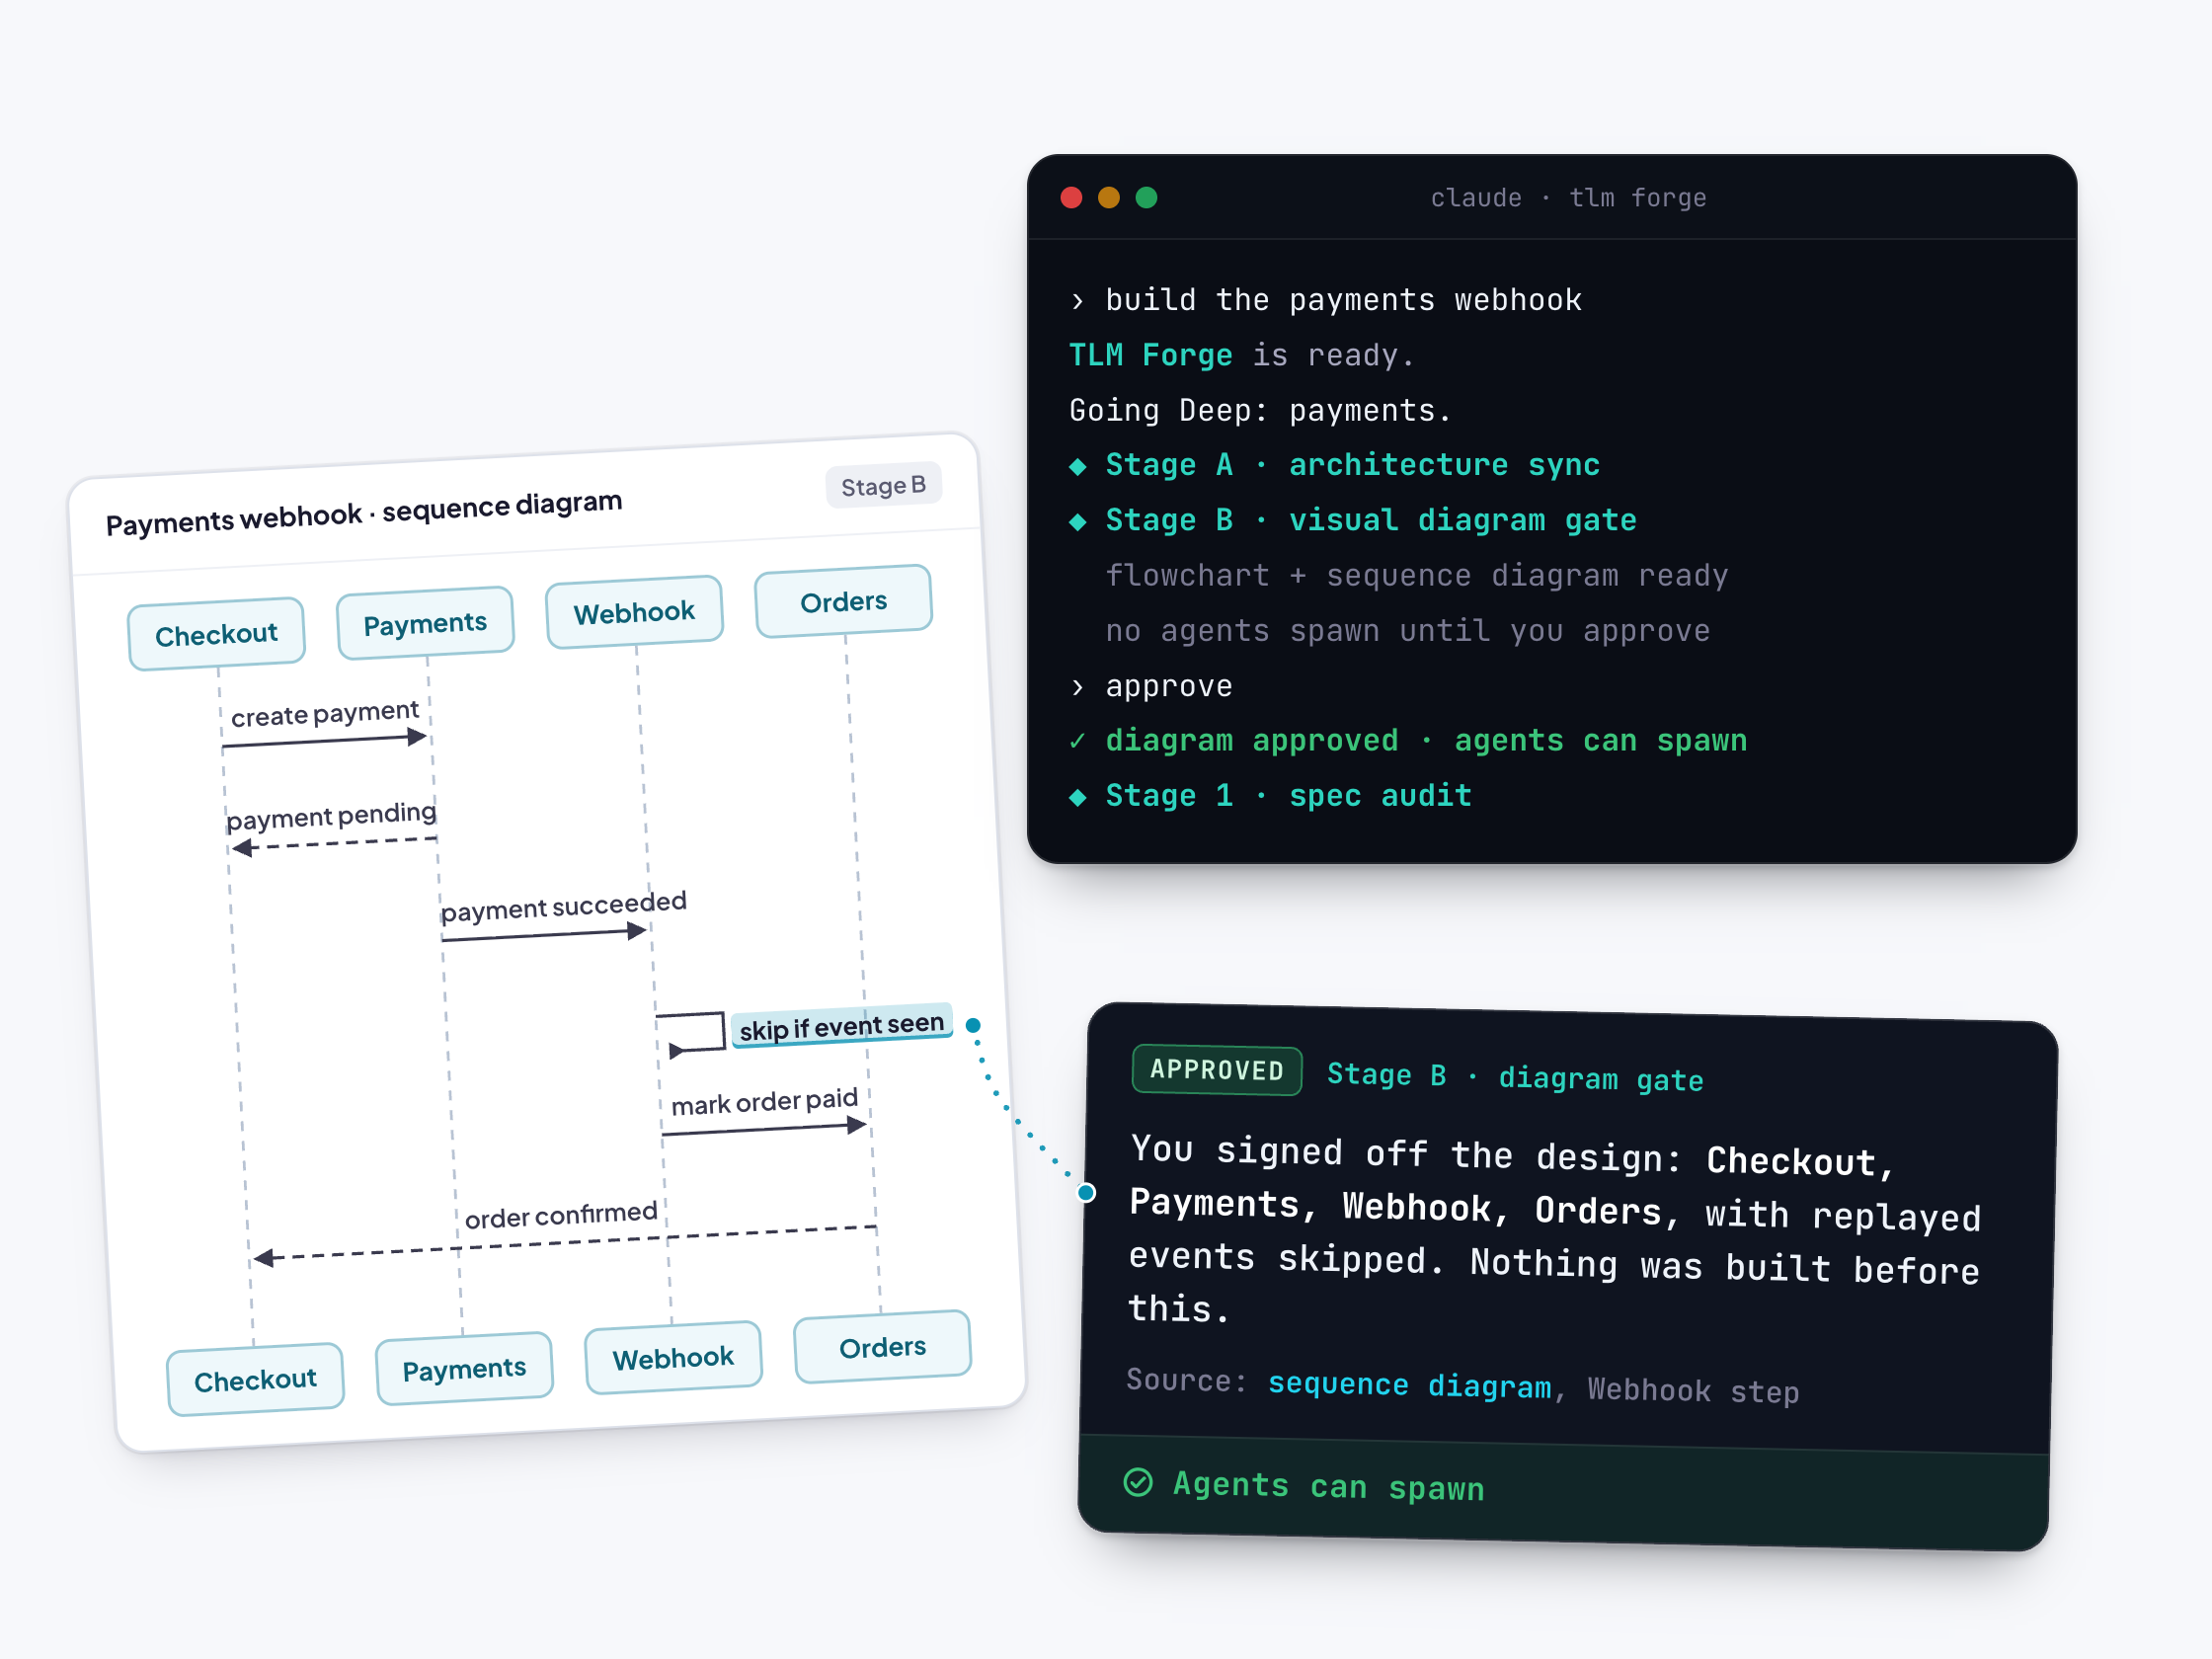
Design sign-off gate
On Medium and Deep work, you get a flowchart and sequence diagram first: nothing builds until you approve it.
Tests first, every phase
Each phase writes failing tests first, RED then GREEN, then commits. Affected tests run while iterating, and the full suite runs at the end of the build, before the final review wave.
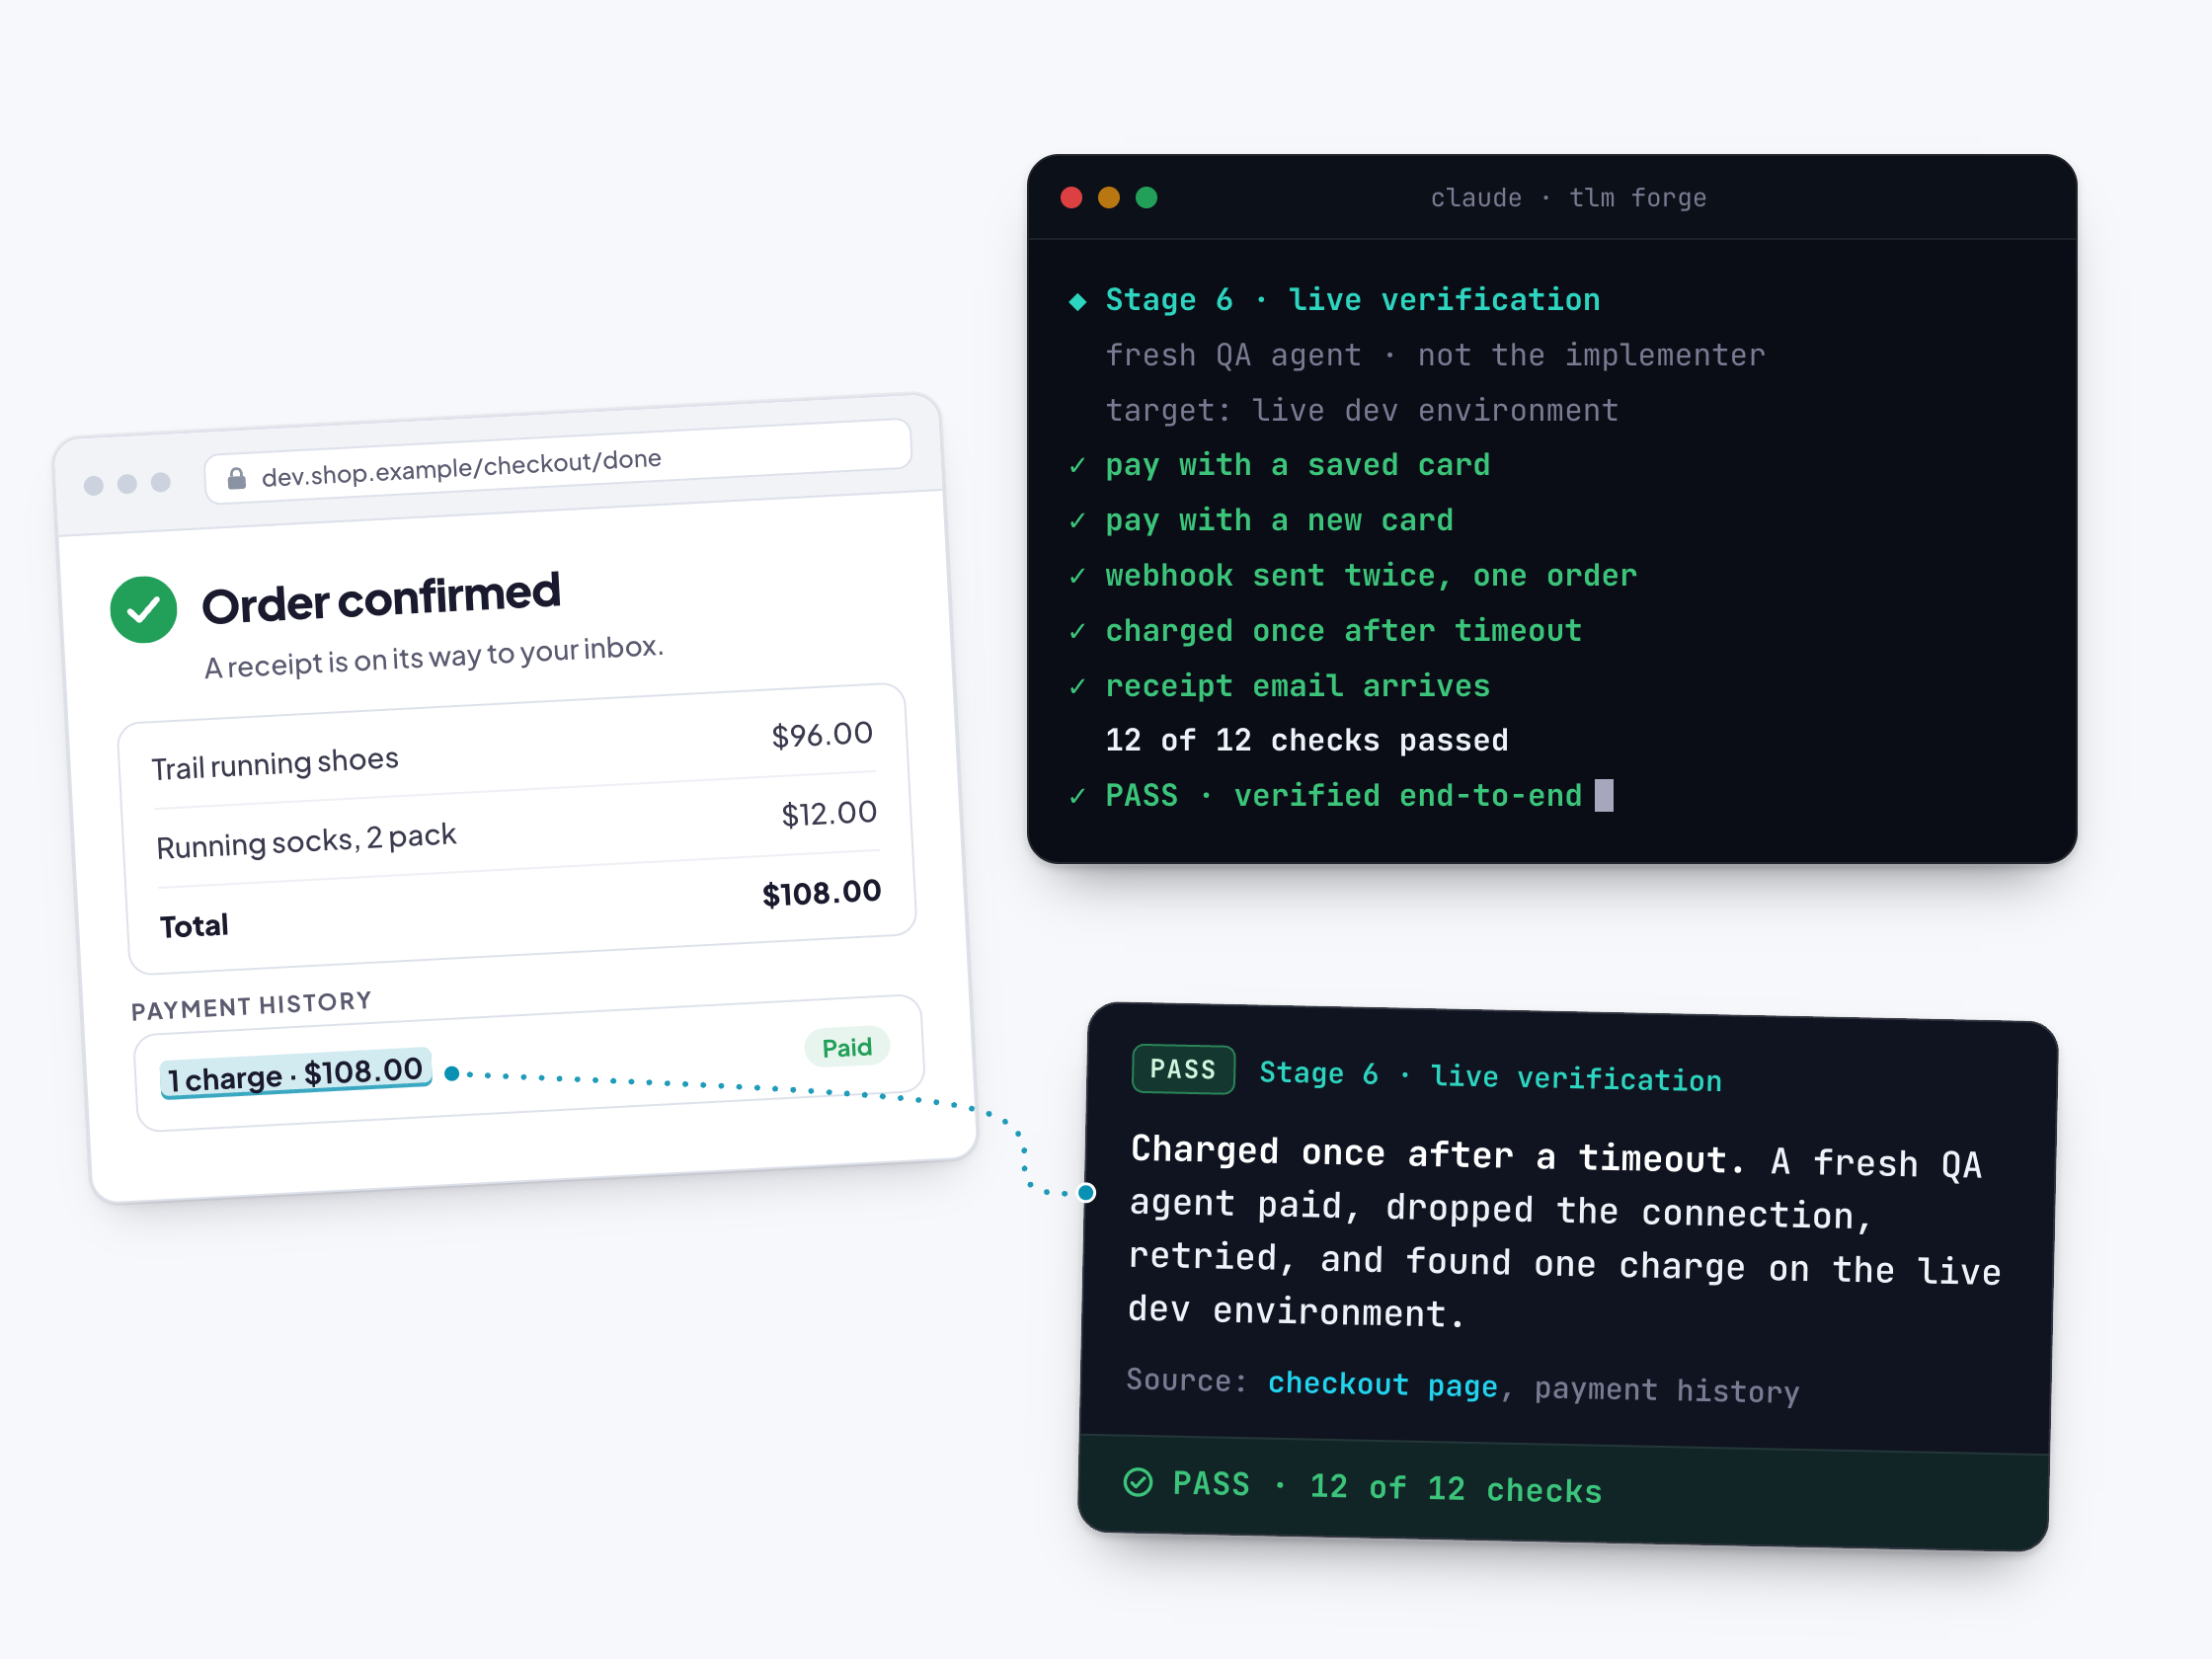
Live verification, end-to-end
On Deep work, the feature is proven on a real deployed environment, not mocks, with the evidence written down: real API output, sample records, and the exact commands to reproduce it.
SHA-anchored commit lock
After the final audit, pushes are blocked if HEAD drifts past the reviewed commit, so no silent changes slip in.
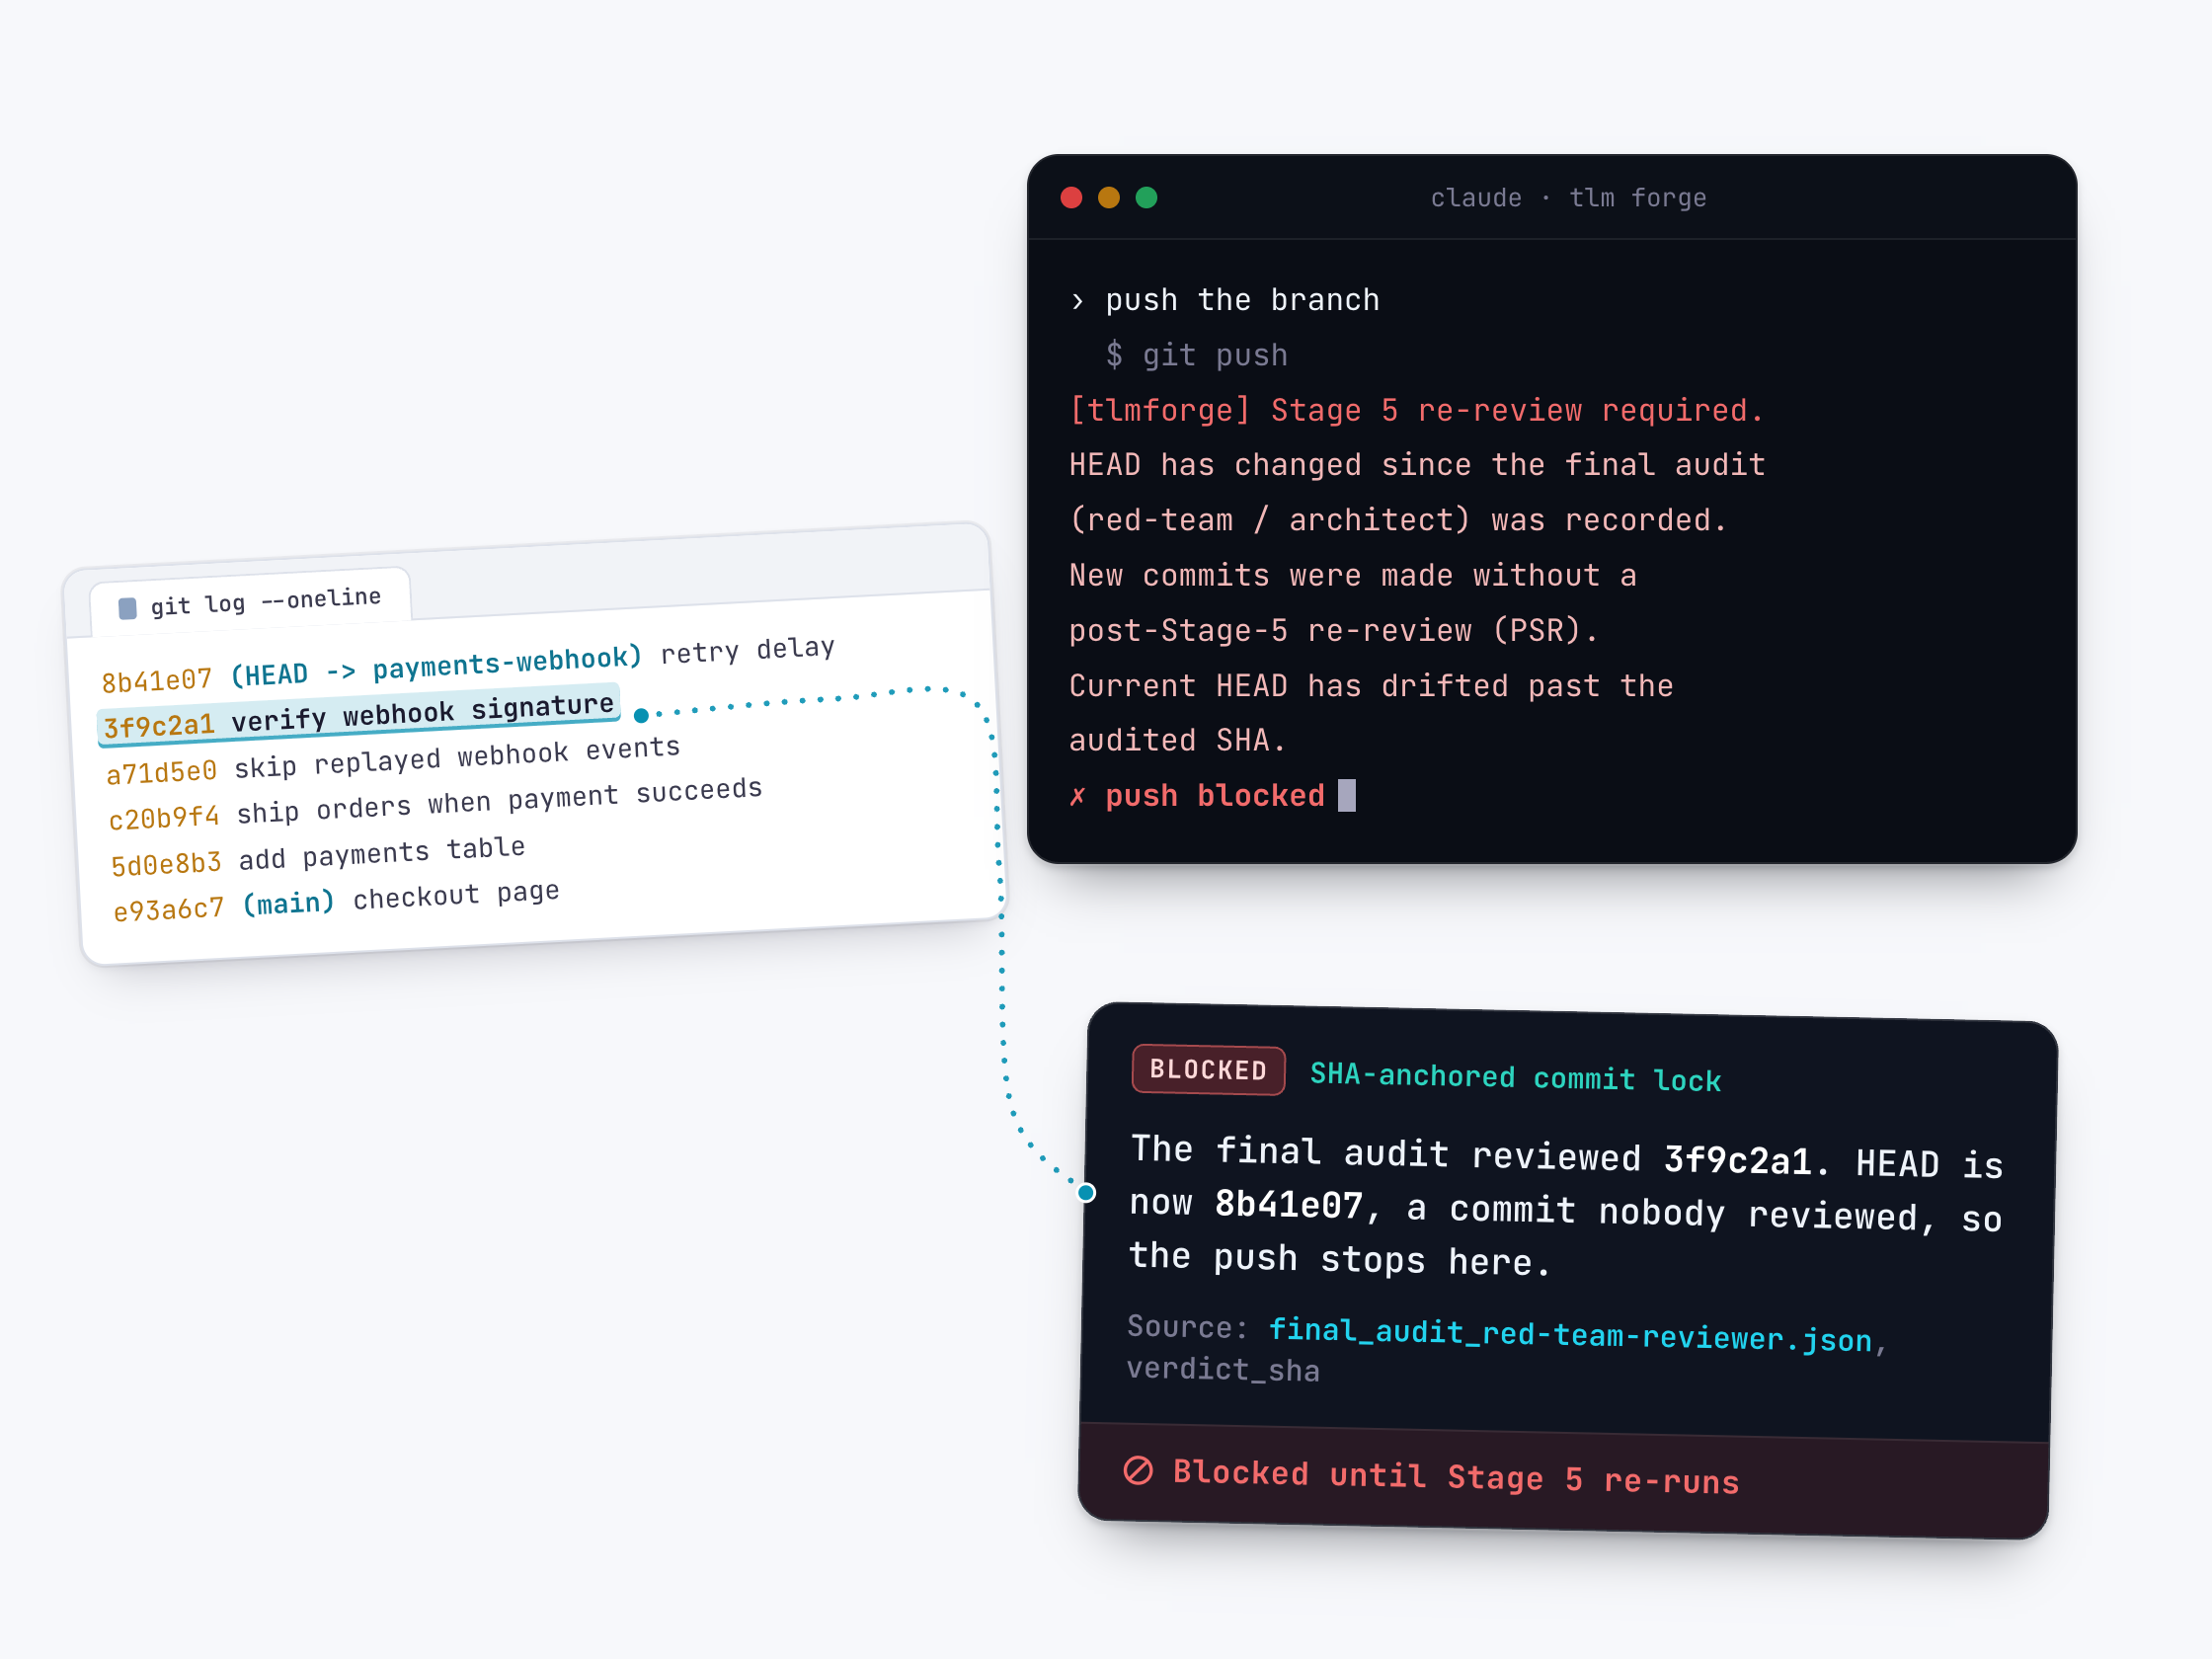
One review wave, one fix wave
The finished diff gets one parallel review wave. Every CRITICAL and HIGH is fixed test-first or brought to you; MEDIUM and LOW go on a written residual list instead of looping forever.
Eight specialists.
Every gap caught before you ship.
The gates above are staffed by a bench of specialist agents. TLM Forge launches each one cold, at the stage where it catches the most, with a single sharp focus: so the threat-modeler isn't swayed by style, and no one reviewer has to catch everything.
Spec-driven, so it builds on itself: never from scratch.
Every reviewer checks the work against the same written spec, plan, and saved proof run instead of re-deriving it, the way a strong engineering team's spec and codebase get sharper over time. That's what lets a full review wave run on every Medium and Deep change, not just the risky ones.
Others structure the work. TLM Forge enforces it.
BMAD-METHOD and GitHub spec-kit help an agent plan. Only TLM Forge blocks the merge until independent, adversarial review says the work is sound.
| Capability | TLM Forge | BMAD | spec-kit |
|---|---|---|---|
| Blocks the merge until every critical issue is resolved | ✓ | — | — |
| Adversarial reviewers: a threat-modeler at design, a red-team on the diff | ✓ | — | — |
| Ship or no-ship is a scored gate, not an opinion | ✓ | — | — |
| Enforced test-driven development with full-suite regression evidence | ✓ | — | — |
| Diagram and goal-contract sign-off before any code is written | ✓ | — | — |
Ship with discipline. Founding-member pricing.
A subscription that pays for itself on the first bug it catches. Cancel anytime, annual is ~70% off the $349.99 list price. Lock in the launch rate.
Based on early-adopter data; your results will vary.
- Versioned design diagrams on a GitHub issueThe design gate posts your flow and sequence diagrams as images to a GitHub issue and re-versions them (v1, v2, v3…) as you give feedback: a reviewable design history, with the issue link surfaced every round.
- Goal contract that runs to completion (/goal)The /goal gate locks the goal, non-goals and measurable exit criteria up front, then keeps building until every criterion is proven, no stopping at 80%, no re-asking "shall I continue?".
- Optimization for future modelsEvery new Claude model is re-tuned day one: prompts optimized to keep your token usage, and your bill, down.
- Early access to every new upgradeNew agents, recipes and improvements reach Pro subscribers first.
- Unlimited runs, no 10-run capFree is capped at 10 total runs so you can try the full recipe; Pro removes the cap entirely.
- Light / Medium / Deep auto-classificationEvery task is auto-triaged into Light, Medium, or Deep so review effort always matches the real risk.
- Full 7-stage feature-development recipeSpec → plan → tests → build → verify → audit → ship, gated end to end so nothing skips a step.
- 8 specialized review agentsDedicated agents for security, performance, correctness and style: architect, tester, threat-modeler, red-team and more.
- Spec audit + independent multi-agent plan reviewRequirements and the implementation plan are vetted before a single line of code is written.
- Phase-gated TDD with a convergence gateTests come first (RED → GREEN), and you literally can't ship until CRITICAL issues hit zero.
- Adversarial red-team audit + SHA-anchored commit lockA final red-team pass, with results pinned to the exact commit SHA they were run against.
- Always up to date, one command: /tlmforge:buildThe methodology is served from the licensed TLM Forge brain and improves continuously, no reinstalls.
- Every Pro feature included
- Bulk discounts, minimum 5 seats
- Centralised billing across your team
- Priority support
We can provide bulk discounts for teams. Minimum 5 seats, tell us your seat count and we'll tailor a quote.
“This one goes deep, reliably succeeds, and fits just how I need it. I've used it for three major features and every time it surfaced details I missed but were critical to catch. So many footguns avoided — saved me days of work down the road.”
 View on LinkedIn →
Questions, answered
Not ready yet?
We drop the price from time to time. Leave your email and we'll let you know when the next price drop arrives, no spam.
Built by an ex-Google Tech Lead & ex-AWS Tech Lead.
The same review discipline that ships at the world's most demanding engineering orgs, packaged for your Claude Code workflow.
Connect on LinkedIn →The same engineering quality as
Google, Apple, and Amazon.
Production-ready code from day one: start free, or go Pro from $34.99/mo.
Get TLMCancel anytime · Secure checkout via Razorpay